Showing posts with label security. Show all posts

Tuesday, May 12, 2026

Agentic AI 2.0 Design Safety Principles

As we graduate from the Agentic AI 1.0 era, we probably should have learned some lessons:

I think you can see where we are going with this. Agentic AI where users have to approve everything is not usable, but Agentic AI where users approve nothing is dangerous and irresponsible. As a middle ground, Agentic AI 2.0 should be designed with the following principles:

  • Well-defined authentication scope that limits an AI agent access to only what is needed to accomplish a task. Each task must be isolated to its own AI agent identity.
  • The authentication scope is a subset of what the human operator has permission to grant.
  • The authentication scope is short-lived (e.g. 1-20 hours) and has a revocation mechanism.
  • Writes and deletes are separate permissions from read, and these operations must be revertible.

In short, the authentication scope should be limited to the task, short lived, and revocable. Use data snapshotting to allow the task to be reverted if anything goes wrong.

Without data snapshotting, the write operation might instead log the before and after diff, and the delete operation might also only mark a resource for soft removal (30 days grace period). Only a human operator is allowed to expunge the data immediately. If this is a database row, instead of deleting a row, the table should probably just have a new "deleted_time" nullable column storing if and when the deletion occurs. The database then periodically vacuums the rows where deleted_time is older than a specific duration set by administrative policy.

At the beginning of a task, the AI agent will propose all the permissions it needs, to be approved by the human operator once until the completion of the task. If the MCP server provides methods to change the world, the MCP is responsible for enforcing the authentication scope and for data snapshotting.

Although the LLM itself without agentic ability is not able to change the world, it is still recommended to run the LLM as its own user or container, as the various PyPI packages needed to run the LLM might be subject to supply chain attack that can lead to local privilege escalation (e.g. through disk cache poisoning).

Tuesday, May 5, 2026

Mitigation strategy for copy.fail and disk cache poisoning of setuid binaries

copy.fail (CVE-2026-31431) is a Linux kernel bug where an in-place modification of a pipe scatter list by the algif_aead module (crypto module's AEAD algorithm) can be used to modify the disk cache of any file, potentially a setuid binary, by an unprivileged user. It allows local privilege escalation from an unprivileged user to root. This vulnerability was a performance optimization presumably introduced in 2017.

The provided exploit is a Python script containing a compressed payload of a ELF x86-64 statically linked binary. The poisoned /usr/bin/su just executes /bin/sh to give a root shell. Contrary to what Low Level claims, this is not shell code. The exploit cannot be shell code for the reason that setuid bit is ignored for shell scripts. This particular exploit will not run on ARM, but a new payload can be trivially crafted for other architectures.

The copy.fail writeup provides a mitigation to prevent the algif_aead module from loading, and the recommendation is to upgrade to a new kernel once it is patched.

The copy.fail writeup also claims that Kubernetes / container clusters are impacted, saying "The page cache is shared across the host. A pod with the right primitives compromises the node and crosses tenant boundaries." This is not generally true because containers often come with its own copy of the filesystem. Each file has to be separately poisoned, and you must somehow convince someone outside of the container to run the poisoned file. Also, the root user 0 in the container is mapped to an unprivileged user in the host, so it will only result in escalation to the container's unprivileged user.

As such, I recommend the following mitigation strategy for disk cache poisoning of setuid binaries:

  • Virtual machine or hypervisor will obviously contain the vulnerability by virtue that each instance runs its own kernel. Cloud compute using virtualization will be fine.
  • Docker or Kubernetes containers will be fine, provided that the host must not share files with the container. Host should also treat any file inside the container as untrusted user data and not run it outside of the container.

The copy.fail vulnerability was also an ad campaign by Theori, a security company, to promote Xint, an AI powered tool to scan for vulnerabilities in source code. It appears to be in the same product category as Claude Mythos.

Update (5/9): Dirty Frag similarly poisons disk cache using two distinct mechanisms, IPSec ESP (CVE-2026-43284) or RxRPC (CVE‑2026‑43500). The exploit also poisons /usr/bin/su to execute /bin/sh. The mitigation strategy above against disk cache poisoning still applies. The IPSec ESP mechanism additionally requires the CAP_NET_ADMIN capability which is not typically granted to unprivileged processes. The RxRPC mechanism can be exploited by unprivileged processes. These mechanisms can be disabled by preventing the kernel modules esp4, esp6, and rxrpc from loading.

Friday, December 12, 2025

Secretive Key Attestation Possible?

On an old MacBook Pro 2019, I've been trying out Secretive (secretive.dev) to let me use the Touch ID (aka SecureEnclave) as a hardware SSH key, like how I would use Yubikey on other computers.

One of the things I would like to do is to create a certificate authority for key signing, to avoid having to manually add new keys to each host I have to SSH into. The certificate authority needs to tell that the hardware key is indeed generated by some qualified hardware, so the private key cannot be easily exfiltrated. Also, I should not be able to cheat by generating a key pair on a computer, making a copy somewhere, then load the private key onto the hardware token and pretend it was generated there.

Normally, using U2F with SSH gives me the option to generate a key attestation that can then be verified by the CA before signing the public key certificate. Essentially, I tell ssh-keygen to write the attestation to another file as the new key is generated, and the attestation will have to be parsed using a custom script in order to check against the vendor certificates published by FIDO2 Alliance.

There are several ways to generate key from the Secure Enclave:

Note that the Secretive 3.0.4 release notes mentions "GitHub attestation" but that is entirely different. It just says the binary built by GitHub actions will now have provenance.

Even though DeviceCheck.DCAppAttestService seems like a likely candidate to generate attested keys, the fact it requires a validation roundtrip to Apple's server can be problematic. It likely only works for apps uploaded to the App Store (which Secretive is not), and people will not be able to compile their own binaries and expect it to work. I'm also not sure how people may feel that Apple can now keep a record of all their SSH keys.

Probably, it's easier to just buy another Yubikey.

Thursday, December 11, 2025

Certificate Signing Request with Authentication Credentials

PKCS #10 (RFC 2986) certificate signing request (X509_REQ) typically contains at minimum the subject and the public key to be signed into a X.509 certificate issued by a certificate authority (CA). Here is an example of what I send to Let's Encrypt:

$ openssl asn1parse -item X509_REQ -in worship.likai.org.csr 
X509_REQ: 
  req_info: 
    version: 0
    subject: CN=worship.likai.org
    pubkey:     X509_PUBKEY: 
      algor: 
        algorithm: id-ecPublicKey (1.2.840.10045.2.1)
        parameter: OBJECT:secp384r1 (1.3.132.0.34)
      public_key:  (0 unused bits)
        0000 - 04 e4 5c 30 85 6f b5 37-35 f4 e9 21 3b 2c 74   ..\0.o.75..!;,t
        ... omitted for brevity ...
        005a - 33 2f c8 fb c1 21 86                           3/...!.
    attributes:
      <EMPTY>
  sig_alg: 
    algorithm: ecdsa-with-SHA256 (1.2.840.10045.4.3.2)
    parameter: <ABSENT>
  signature:  (0 unused bits)
    0000 - 30 66 02 31 00 ce 23 b9-c3 b0 53 24 2f d3 8c b0   0f.1..#...S$/...
    ... omitted for brevity ...
    0060 - cc fe a2 64 fa f2 7a e6-                          ...d..z.

X509_REQ can also contain extensions, most notably subjectAltName. Some of the extensions are documented in x509v3_config, which includes the ability to send arbitrary extensions. PKCS #9 (RFC 2985) defines the attributes that can be used in a PKCS #10 CSR. Arbitrary extensions are defined by an object identifier (OID) key and some ASN.1 value. We can lookup the OID assignments.

As currently defined, X509_REQ does not have the ability to include authentication credentials, i.e. the CA only knows the subject and its public key, and the X509_REQ itself is signed by the same subject's public key for integrity, but the CA does not know whether the subject is whom they claim to be.

That kind of trust has to be verified out of band. In the case of Let's Encrypt (how it works), the ACME protocol performs domain validation by fetching the result of a challenge response over plaintext HTTP at the domain name matching the CN subject in the CSR. This requires the host to be reachable from the public Internet, which is not feasible for internal servers. There are other challenge types: TLS-ALPN-01 also requires the host to be reachable from the public Internet; DNS-01 does not require the host to be reachable, but the requestor must be able to modify the DNS record, which can present other difficulties.

Enrollment over Secure Transport (EST) is another protocol to automate certificate signing (like ACME). It authenticates the CSR at the API layer but not as part of the CSR. However, binding the API authentication to the CSR remains a challenge.

There are a few potential OIDs we can investigate for their suitability to include authentication credential as part of the CSR:

  • PKCS #9 defines a challengePassword OID 1.2.840.113549.1.9.7, but it is supposedly used to request certificate revocation. It seems to be unimplemented. Also, it is generally a bad idea to repurpose a field for a different purpose than originally intended.
    • The content of challengePassword is plaintext equivalent, which means the CSR should be protected by other means so it is not public accessible.
  • RFC 7894 proposes additional fields to disambiguate the PKCS #9 challengePassword, notably: otpChallenge, revocationChallenge, estIdentityLinking.
    • It assumes that the primary authentication is done by the underlying transport such as EST. The additional fields can provide a second-factor authentication.
  • The SMI mechanism OID 1.3.6.1.5.5 references additional mechanisms tracked by IANA. In particular:
    • The aforementioned RFC 7894.
    • There is a working draft draft-ietf-lamps-csr-attestation-08 to attest the CSR with evidence, which is intended to come from a hardware TPM or PSA. Presumably, the evidence can be further extended to cover FIDO U2F or Passkeys. These evidences must not contain plaintext equivalent secrets.
  • Kerberos OID 1.2.840.113554.1.2.2 (RFC 1964) does not have an OID for the challenge response, as far as I can tell.

These proposals tend to avoid putting plaintext secrets into CSR, but the ability to secure secret credentials in a CSR remains elusive.

Envelope Proposal

To be able to include secrets in CSR, we can use the CA's public key to encrypt the plaintext, and we store the ciphertext in an envelopedData. There are three potential OIDs defining envelopedData:

The envelopedData defined by PKCS #7 (RFC 2315) is obsolete by the latest version RFC 5652, which seems to be the correct candidate to store encrypted secrets destined for the CA. If the CA has multiple certificates, they can all be included as a recipientInfo.

Inside the envelopedData should be a SEQUENCE that contains at least the SET OF Attribute{{ IOSet }} as defined in PKCS #10 (RFC 2986). This also opens up the possibility to include anything from an LDAP directory OID 2.5.4 (RFC 4519 or ISO/IEC 9594-6:2020 or X.520) that might need to be protected from public access, such as userPassword 2.5.4.35 or maybe encryptedUserPassword 2.5.4.35.2.

Afterthoughts

On one hand, having a global OID means applications and protocols can share relevant definitions when appropriate, but navigating the maze of existing OID assignments can be an exercise in frustration. It is similar to code reuse: sometimes the code you borrow from almost does what you need except for some corner cases, but you cannot change the corner case behavior because it may break existing users relying specifically on the corner case. So you have to choose the OID carefully based on how you expect the OID to evolve in the future, and try to find an OID that best aligns with the use case.

It is tempting to start from scratch and define exactly what an application needs in an application-specific way without any historical baggage, like JOSE (JWS/JWT). Their RFCs are still long, but still shorter than the maze of OIDs, RFCs, and ITU/ISO standards. It would be nearly trivial to abbreviate the CSR to another JSON object.

It is also interesting how OID leaves the breadcrumbs showing how the Internet standards evolved. At first, RSA developed the PKCS under its OID 1.2.840.113549 {iso(1) member-body(2) us(840) rsadsi(113549)}, then this namespace is donated to IANA. Similarly, the OID 1.3.6.1 {iso(1) identified-organization(3) dod(6) internet(1)} used to be owned by DoD (Department of Defense), now hijacked by IANA as well.

Tuesday, December 9, 2025

Runtime TLS Certificate Hot-Reload with OpenSSL

For long-running microservices that can act as both client and server, it is possible the lifetime of the microservice might outlive its TLS certificate validity, especially if an organization opts for a security policy to rotate TLS certificates quickly (e.g. every day). We need to be able to reload both the client and server certificates without exiting the service.

OpenSSL provides the functionality as follows:

  • For a client, the caller should use SSL_CTX_set_client_cert_cb() to provide a callback which is "called when a client certificate is requested by a server and no certificate was yet set for the SSL object." The caller provides a client_cert_cb() function that modifies the X509 ** and EVP_PKEY ** (pointer to a pointer), which OpenSSL will use to call SSL_use_certificate() and SSL_use_private_key() internally.
  • For a server, the caller should use SSL_CTX_set_tlsext_servername_callback() to provide a callback which is called during SNI. The caller provides a cb() function that modifies the SSL * object directly to override the SSL_CTX using SSL_set_SSL_CTX().

The callback can use an out-of-band method to reload the private key and certificate as needed. Once a connection has been authenticated during handshake, it will probably remain active even after the certificate expires, so the callbacks only apply to new connections.

To actively disconnect TLS transport with an expired certificate, some kind of connection pool management will be needed to wrap OpenSSL. This connection pool can also handle load balancing.

It is generally a good idea to allow certificate rotation to have some validity overlap so connections can be "upgraded" to the new certificates gradually. It avoids the problem where all connections die and have to be reconnected all at once, which can have undesirable latency impact.

Friday, March 29, 2024

Mitigation strategy for SSH server supply chain attack

A backdoor compromising SSH server introduced in xz/liblzma 5.6.0 and 5.6.1 was reported today to oss-security by Andres Freund. According to the analysis, when the sshd binary is initialized by the dynamic linker at startup, the initialization code in liblzma installs a hook to the dynamic linker that modifies subsequent dynamic library symbol tables (before they are made read-only) that replaces SSH RSA encryption functions with malicious code.

Image credit: Wikimedia Commons

The xz repository provides a widely used data compression command line program “xz” as well as a library “liblzma” that allows the compression algorithm to be used in other programs. SSH is a remote secure login server. Although SSH does not use liblzma directly, many distributions such as Debian and Redhat patches it to integrate with systemd notification, which uses liblzma.

The malicious code in liblzma was introduced as obfuscated binary test data in a git commit and patched into compiled binary using an obfuscated M4 macro as part of the build system. The malicious git commit was introduced by JiaT75, who has been contributing xz commits for about two years while taking advantage of the mental health issues of the original author of xz, who maintained it as an unpaid hobby project. Most of Jia's commits are non-technical fixes such as translation or documentation. Jia reportedly urged Redhat and Debian maintainers of the xz package to push the new version to production, which suggests that it is premeditated. The attack was only discovered because Andres Freund noticed that his SSH login got slower and decided to investigate.

It is nearly impossible to manually audit supply chain attacks like this, but there is one way to mitigate this attack vector: all setuid binaries should be statically linked with the static-PIE linking option. Static linking eliminates the dynamic linking attack vector, while PIE enables address-space layout randomization (ASLR) to make it impossible for malicious actors to patch code in runtime. Allegedly, OpenBSD already compiles system binaries this way.

Some may have concerns about static linking, but they can read the refutation by Gavin D. Howard.

Advisory About Go

Static linking alone does not completely guard against runtime code patching, but we need address-space layout randomization (ASLR) for both code and data. That is because the data sections also contain function pointers that could alter the code path. Without ASLR for data, any function pointer in heap-allocated objects can be compromised by supply chain attack.

Go does not support heap data ASLR (golang/go#27583). This means that malicious code using the unsafe package could traverse the heap and override interface function pointers to change the behavior of existing code. This is despite the fact that Go language always compiles and statically links on the whole-program, and has a -buildmode=pie for code ASLR. Unfortunately, the Go crypto, ssh, tls, and net/http packages all make ample use of interfaces, and every one of these can be an attack vector.

Saturday, March 16, 2024

Carrot and Stick Security Design

Carrot and stick security design is the idea to have frontend and backend work together to enforce security policies in software. The frontend interacts with the user and steers them towards compliance, while the backend enforces the security rules. Although we don’t necessarily use carrot and stick to mean reward and punishment, the carrot is a “soft nudge” and the stick is a “hard boundary.” If the user bypasses the frontend and tries to interact with the backend directly, they will be met with a hard error message.


Image credit: Wikimedia Commons

(“Good cop, bad cop” is a similar strategy, although the cop analogy may be controversial.)

An example is a photo gallery that allows visitors to browse but only signed-in users to download images. The frontend may present a “download” button but will ask the user to either login or create an account. The backend checks that the login credentials are present before allowing the image to be downloaded.

If the security check is only done in the frontend, then the user could simply bypass login by forging a URL request directly to download the images. If the security check is only done in the backend, then an innocent user that did not know they need to signup or login first may be confronted with an unfriendly error message.

I’m intentionally using the terms “frontend” and “backend” loosely. In practice, the designations may differ depending on the application:

  • For a user-facing website, frontend is the client side Javascript, and backend is the HTTP server.
  • For a mobile app, frontend is the app, and backend is some API used by the app.
  • For an API, frontend is the HTTP server middleware, and backend is the internal data storage.

Even at the API level, the API design should try to encourage well-defined use cases (the carrot), and let the protocol layer check for malformed requests (the stick).

What this means is that a complete software stack that spans the gamut of client side Javascript or app, an API middleware, and backend storage should implement security enforcement at all layers.

Friday, March 1, 2024

Memory Safety State of the Union 2024, Rationale Explained

There has been renewed interest in programming languages after The White House recently published a recommendation suggesting the transition to a memory safe language as a national security objective. Although I am not an author of the report, I want to explain the rationale that someone might use to consider whether their infrastructure meets the memory safety recommendations. This is more of an executive-level overview than a technical guide to programmers.

Image credit: Wikimedia Commons, Whitehouse North.

On February 26, 2024, the White House released Statements of Support for Software Measurability and Memory Safety calling attention to a technical report from the Office of the National Cyber Director titled “Back to the Building Blocks: A Path Towards Secure and Measurable Software” (PDF link). The whole framework works like this: we ultimately want to be able to measure how good the software is (e.g. by giving it a score), and it relies on memory safety as a signal. The tech report also references another report published by Cybersecurity and Infrastructure Security Agency (CISA) titled The Case for Memory Safe Roadmaps which contains a list of memory safe language recommendations.

To supplement their list, I will be using the TIOBE index top 20 most popular programming languages to provide the examples: Python, C, C++, Java, C#, JavaScript, SQL, Go, Visual Basic, PHP, Fortran, Pascal (Delphi), MATLAB, assembly language, Scratch, Swift, Kotlin, Rust, COBOL, Ruby.

I will also throw in some of my personal favorites: LISP, Objective Caml, Haskell, Shell, Awk, Perl, Lua, and ATS-lang.

High Level Languages

Languages that do not expose memory access to the programmer tend to be memory safe. The reason is that it reduces the opportunity for programmers to make memory violation mistakes. When accessing a null pointer or an array with an out of bounds index, these languages raise an exception that could be caught, or return a sentinel value (0 or undefined value), rather than silently corrupting memory content.

Examples: Python, Java, C#, JavaScript, SQL, Go, Visual Basic, PHP, MATLAB, Scratch, Kotlin, Ruby; LISP, Objective CAML, Haskell, Shell, Perl, Awk, Lua.

Under the hood, they employ an automatic memory management strategy such as reference counting or garbage collection, but programmers will have little to no influence over it because the language does not expose memory access.

It does not matter whether the language execution happens at the abstract syntax tree (AST) level, compiled to a byte code, or compiled to machine code. In general, any language could have a runtime implementation that spans the whole spectrum through Just In Time compilation.

Things to Watch Out For

High level languages are prone to unsanitized data execution error such as SQL injection, Code Injection, and most recently Log4j. This happens when user input is passed through to a privileged execution environment and treated as executable code. High level languages often blur the line between data and code, so extra care must be taken to separate data from code execution. Data validation helps, but ultimately data should not have influence over code behavior unless it is explicitly designed to do so.

I strongly oppose using PHP or any products written in PHP, which is particularly notorious for SQL and code injection problems and single handedly responsible for all highly critical WordPress vulnerabilities. But if you inherited legacy infrastructure in PHP, there are principles that will help hardening it.

Even though memory access errors are raised as an exception, if these exceptions are not caught, they could still cause the entire program to abort. They also still allow potentially unbounded memory consumption leading to exhaustion, which causes program to abort or suffer severely degraded performance, leading to denial of service.

Some languages provide an “unsafe” module which is essentially a backdoor to memory access. Using them is inherently unsafe.

Most languages also allow binding with an unsafe language through a Foreign Function Interface (ffi) like SWIG. This allows the high level code to run potentially unsafe code written in a non-safe language like C or C++.

Mid Level Languages

These languages expose some aspects of memory management to the programmer—such as explicit reference counting—and provides language facilities to make it safer.

Examples: Swift, Rust; also ATS-lang.

Performance is the main reason to use these languages, as memory management overheads have negative performance impact, and in some time-sensitive applications, we have to carefully control when to incur these overheads. The tradeoff is programmer productivity, since they have to worry about more things. Since performance is the main concern, these languages tend to be compiled into machine code before running in production.

I want to call out ATS-lang because it is a language I helped working on for my Ph.D. advisor, Hongwei Xi. It was conceived in 2002 and predated Rust (2015). ATS code can mostly be written like Standard ML or Objective CAML with fully automatic memory management. It also provides facilities to do manual memory management. Safety is ensured by requiring programmers to write theorems to prove that the code uses the memory in a safe manner (papers). The theorem checker uses stateful views inspired by linear logic to reason about acquisition, transferring of ownership, and disposal of resources.

Things to Watch Out For

These languages are safe by virtue that the compiler can check for most programmer errors in compile time, but these languages still provided unsafe ways to access memory.

Furthermore, they are still prone to denial of service, SQL injection, and code injection vulnerabilities.

Low Level Languages

These languages require the programmer to manually handle all aspects of memory management for legacy reasons. For this reason, they are inherently unsafe.

Examples: C, C++, Pascal.

Although garbage collection was invented by John McCarthy in 1959 for the LISP language, that concept did not gain mainstream adoption until much later.

Even so, there are a few strategies to make these languages more memory friendly.

  1. Use an add-on garbage collector like Boehm-GC. Note that object references stored in the system malloc heap are not traced for liveness, so care must be taken when using both GC malloc and system malloc.
  2. C++ code should use Resource Acquisition is Initialization (RAII) idiom as much as possible. The language already tracks object lifetime through variable scope. The constructor is called when an object is introduced into the scope, and the destructor is called when the object leaves the scope. Smart pointers like std::unique_ptr and std::shared_ptr use RAII to manage memory automatically.

My particular contribution in this field is my Ph.D. dissertation (2014), which proposed a different type of smart pointer in C++ that does not auto-free memory but still helps catching memory errors. I showed that it is practical to use, by implementing a memory allocator using the proposed smart pointer.

Legacy Languages

I have omitted Fortran and COBOL from any of the lists above. Historically, Fortran and COBOL only allowed static memory management. All the memory to be used by the program are declared in the code, and the OS provisions for them before the program is loaded for execution. However, they never had any array bounds checking, so they are not memory safe. Furthermore, attempts to modernize the language with dynamic memory allocation exacerbated the problem that these languages were not designed to be memory safe.

I have also omitted assembly languages as a whole. Assembly languages tend to be bare metal and provide completely unfettered memory access, but there have been some research to enhance the safety of assembly languages (e.g. Typed Assembly Language).

Conclusion

There is no language that is completely memory safe. Some languages are safer by design because either it limits the ability of the programmer to manipulate memory, or it gives the programmer facilities to help them use memory in a safer way. However, almost all languages have ways to unsafely access memory in practice.

Memory safety is also not the only way to cause security breach. Executing data as code is the main reason behind SQL and code injection, and these lead to highly critical privilege escalation, penetration, and data leak attacks. One safety net we can provide is by making code read-only, but this does not absolve the importance of good data hygiene.

Unbounded memory consumption can degrade performance or cause denial of service attacks, so memory usage planning must be considered in the infrastructure design.

In any case, the language is not the panacea to the memory safety or security problems. Programmer training and a culture to emphasize good engineering principles are paramount. However, I would love to see a renewed interest in programming language research to enhance language safety, by designing languages that encourage good practices.

Further Resources

Sunday, June 12, 2022

Designing a Data Breach Resilient Database

Rainbow crepe cake, by The Cooking of Joy.

With several high profile data breach settlements—such as Equifax and Morgan Stanley—coming to a conclusion, it begs the question: how do we prevent these data breaches from happening in the first place?

In the case of Equifax, attackers gained unauthorized access via their dispute portal website which allowed them to discover credential to the central database keeping the customer data, and they slowly exfiltrated that data over 76 days to avoid detection.

In the case of Morgan Stanley, the data breach was caused by improper disposal of used hard drives containing customer data.

Security is always as strong as the weakest link, so if we want to prevent future data breach, we have to understand how the storage stack works. It's helpful to think of storage as a layered model like how the OSI model (Open Systems Interconnection) helps us understand networking. We can tentatively call this the DSI model (Data Storage Interconnection). There is a straightforward analogy of the layers between these two models.

To recap, here are the OSI layers.


OSI model

OSIDescription
7*Application LayerA website or app that the user interacts with.
6*Presentation LayerInterpretation of the data, e.g. HTML, JSON, UTF-8.
5*Session LayerDefinition of request and response semantics, e.g. HTTP, gRPC.
4Transport LayerData transmission and flow control, e.g. TCP, UDP.
3Network LayerRouting of data between networks, e.g. IPv4, IPv6.
2Datalink LayerNode identification on a local network, e.g. Ethernet MAC.
1Physical LayerModulation of bits on a physical medium, e.g. 10GBASE-T.

* Note: The original OSI model specification only specified the purpose of each layer but not concrete examples of standards. Traditionally, HTTP is considered an "application" known as the web browser, but these days HTTP is also used for a transport like gRPC, which pushes it down to a lower layer. My definition here reflects the modern web2 or web3 stacking.


DSI model
DSIDescription
7Application LayerA website or app that the user interacts with.
6Presentation LayerInterpretation of the data, e.g. HTML, JSON, UTF-8.
5Schema LayerModeling of data, e.g. table definitions.
4Database LayerTransaction and indexing, e.g. SQL.
3Filesystem LayerAbstraction for files and directories, e.g. ZFS, NTFS, AWS S3.
2Block LayerBlock devices, e.g. SCSI, SATA.
1Physical LayerModulation of bits on a physical medium, e.g. SMR.

In a similar fashion, we can define data storage layers that are roughly analogous to the OSI layers. Application Layer and Presentation Layer are the same, but layers 5 and below are redefined for data storage purposes. Physical Layer has the same purpose again.

(As a side note, the Presentation Layer and Schema/Session Layer are typically where difficulties may arise when sharing data between different companies, for example to provide universal access to health records, and this is true both in the networking and data storage sense. But that's a topic for another day.)

As we can see, the Morgan Stanley data breach happened at the Physical Layer. The Equifax breach started at the Application Layer, but the data is exfiltrated at the Database Layer. However, data breach can happen at other layers too. Here is a summary of risk factors at each layer.


DSI attack vectors
DSIDescription
7Application LayerA vulnerable website allowing access to lower layer credentials, e.g. Equifax.
6Presentation LayerCross-site scripting, where malicious code is injected through data.
5Schema LayerEnumeration attack due to poorly designed data access policies.
4Database LayerExfiltration of data (e.g. Equifax), SQL injection attack.
3Filesystem LayerLocal privilege escalation.
2Block LayerNetwork attached storage in an unsecured network or using an insecure protocol.
1Physical LayerTheft or improper disposal of physical medium, e.g. Morgan Stanley.

* Note: as new attack techniques become known, I'll add them to the correct layer here.


It is tempting to try to put all security burden on the Application Layer, but it is unrealistic to expect that a single layer can handle all the attacks thrown at it. Again, since security is only as strong as the weakest link, we have to fortify each layer.

Application Layer should impose a strict separation of code and data. When possible, the application should be implemented using a compiled language with code placed in a read-only filesystem (see Revival of Harvard Architecture). The application should be shielded behind a monitoring system for detecting unusual access patterns, but reconnaissance alone is not enough. It is often already too late when the exploit is detected, but we still want to have real-time signal for exploit attempts.

Presentation Layer should escape data consistently when inserting one piece of data into another. User-supplied HTML should be parsed and scrubbed to keep only allowlisted elements. A proper templating library should be able to handle that. Don't use string concatenation for structural data.

Schema Layer should use itemized encryption as a means to control the sharing of data. Data is considered shared with someone if they have access to the session key for that data. One way to do this is to encrypt the item key for anyone that should have read access to the item. The user has an encrypted item key that can be decrypted by a credential of their choice. If the backend system requires access to the item, the item key will additionally be encrypted for the backend's role account credential.

Since anyone who has access to the item key will have access to all data encrypted by that item key, data should be scoped for the reader. Data for a different set of readers should be encrypted by its own item key. Nevertheless, access to the item's cipher-text should still be subject under an access-control list. Even though itemized encryption alone should prevent the enumeration attack, the additional access-control list guards against improperly designed itemized encryption key schedule or derivation.

Database Layer should apply a page-level encryption (such as SQLite Encryption Extension) even though user data is already encrypted by the Schema Layer. This allows Filesystem Layer to replicate or backup the database without worrying that some tables or indices may still contain unencrypted sensitive data.

We do not presently require the Filesystem Layer to implement any mitigation. This allows industry-standard data availability and redundancy practices to continue to be deployed. Vulnerability at this layer comes from the OS vendor and is typically outside of our control, so we mitigate this by having encryption at the Database Layer and the Block Layer.

Block Layer or Bit Layer should apply full-disk encryption so that it is impossible to recover data without the volume encryption key if the storage medium is improperly disposed. Encryption at this level alone is not enough because in case of a stolen laptop, a copy of the decryption key would still be found in system memory somewhere. And there is a good chance that the residual key can still be recovered after the laptop is powered off, e.g. by cryogenically freezing the RAM.

In summary, mitigation strategies tailored for each data storage layer together provide a defense in depth. Reasoning using the DSI model allows us to clearly see how the separation of concerns at each layer contribute to the overall mitigation strategy. And this is how to design a data-breach resilient database.

Thursday, July 15, 2021

Revival of Harvard Architecture for the Mitigation of Ransomware Attacks

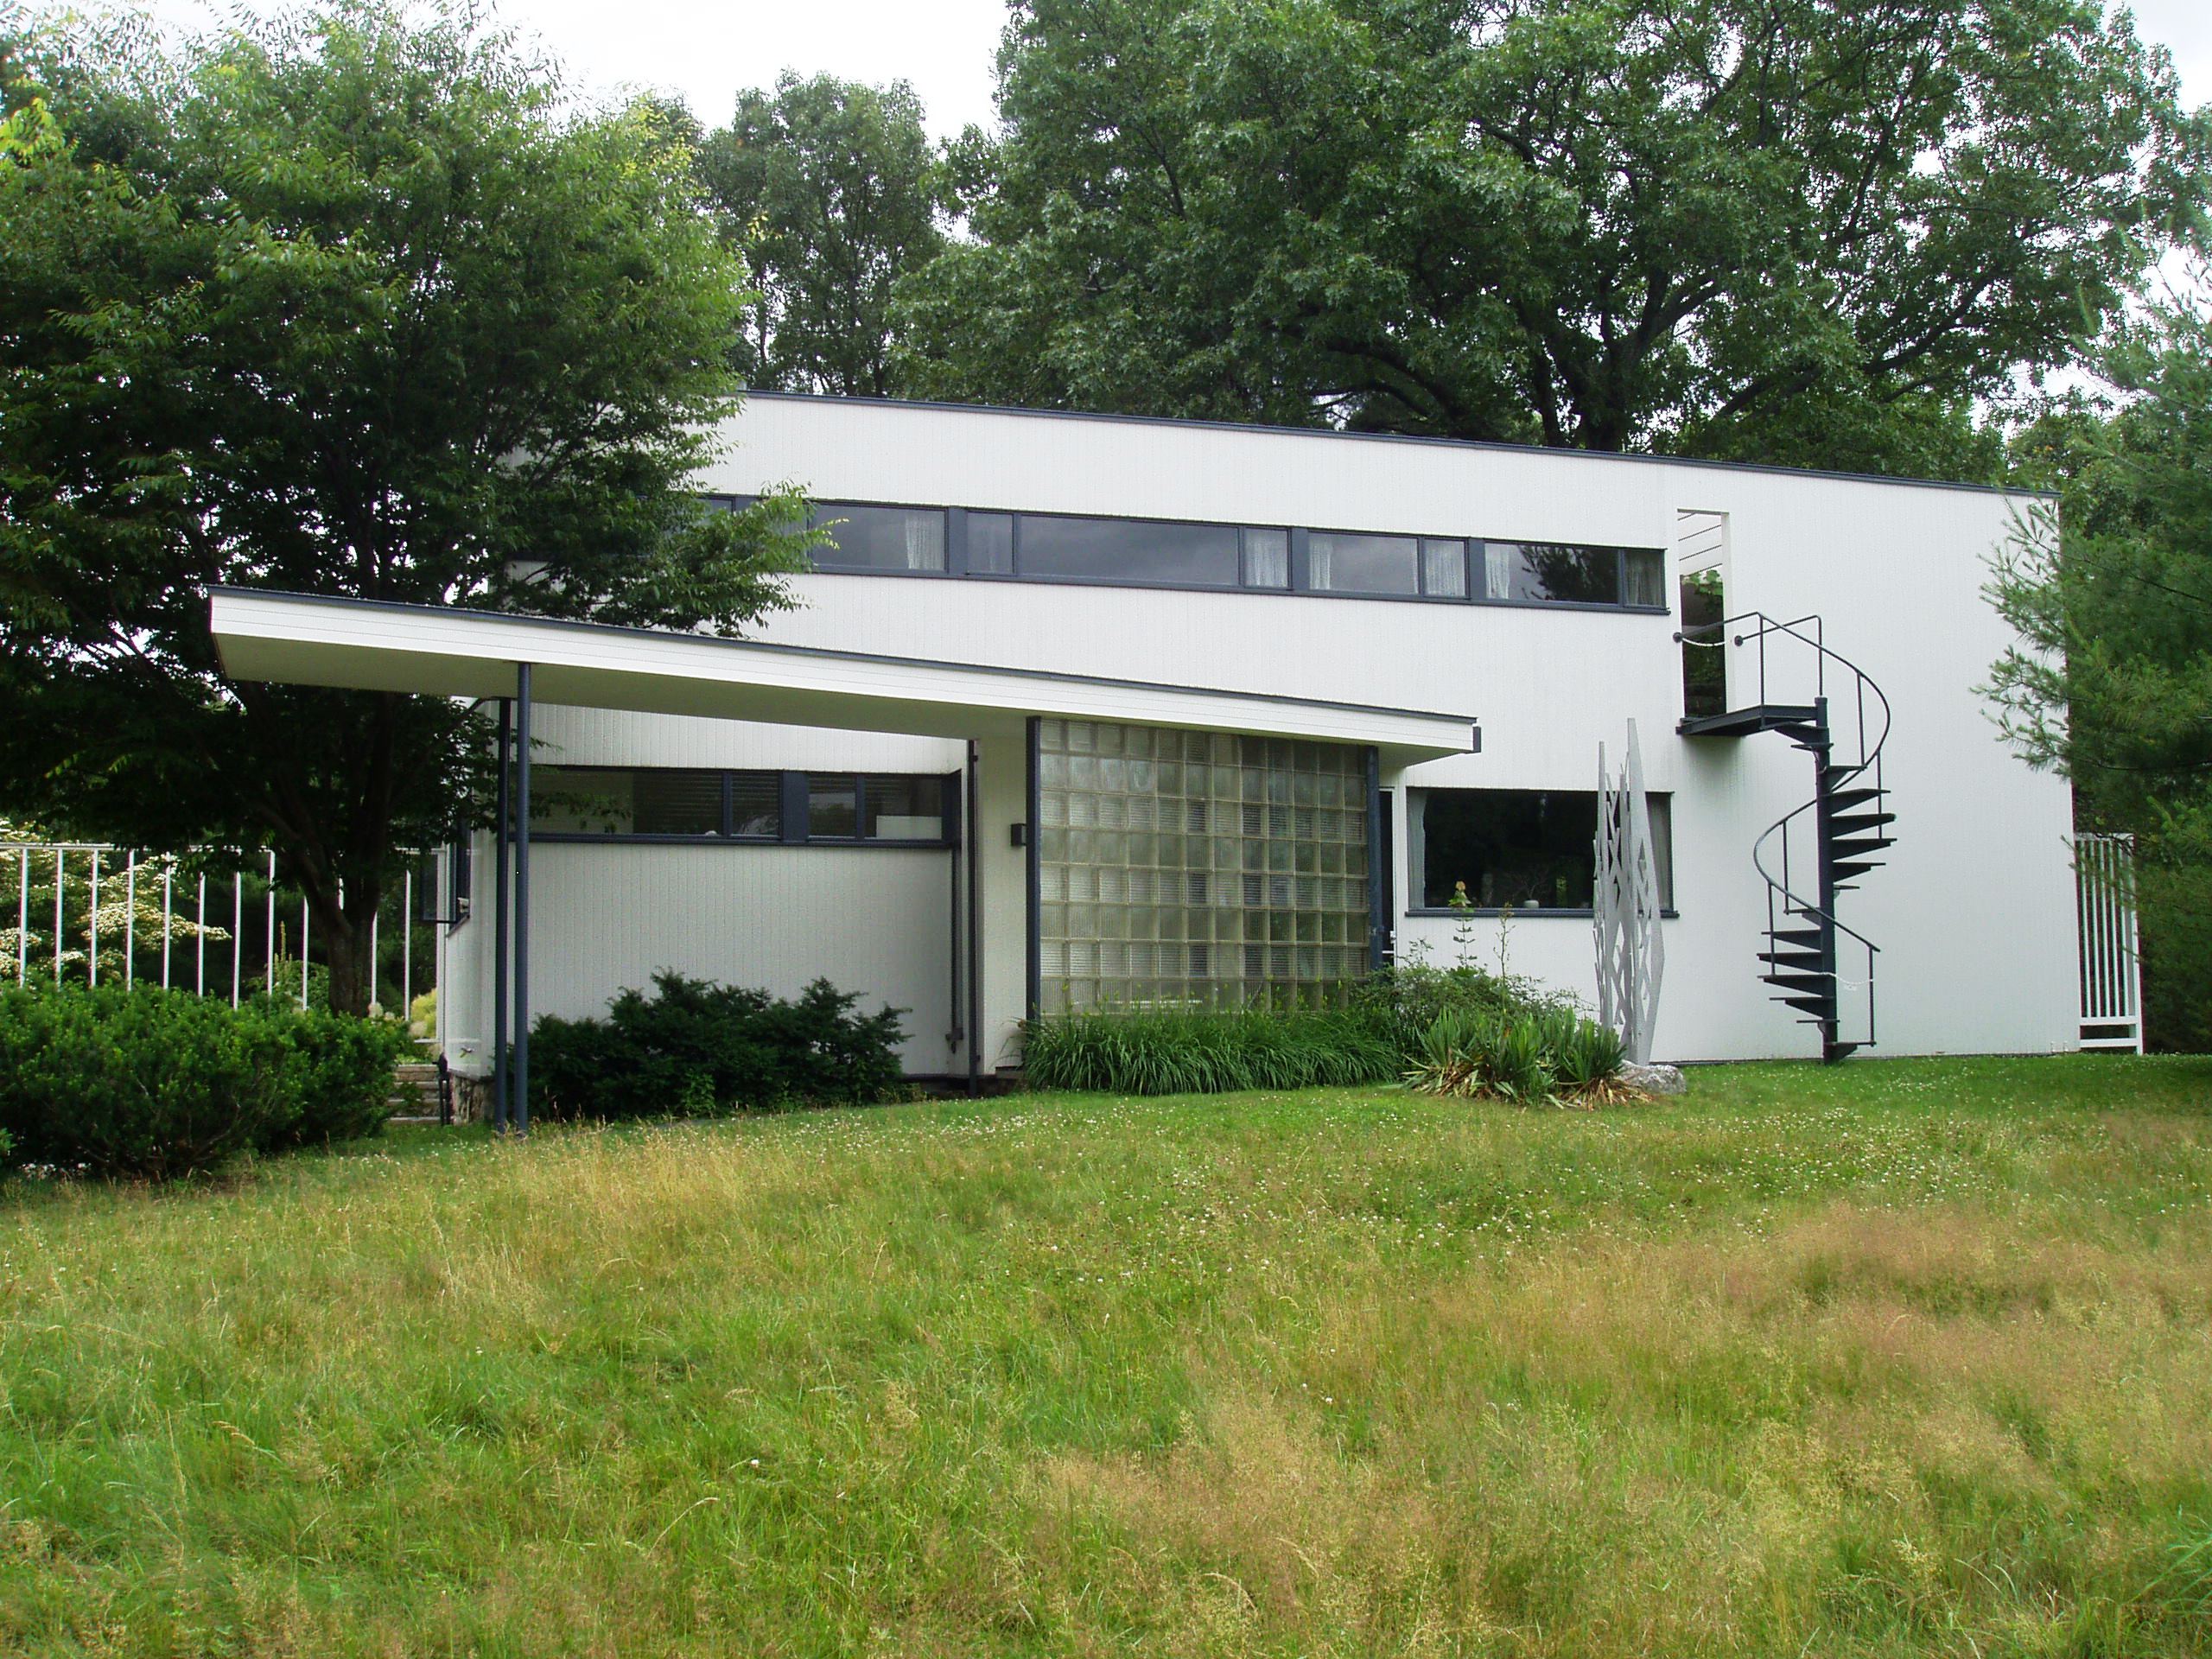
Pictured below is the Gropius House in Lincoln, Massachusetts, which was the former residence designed and built by the renowned architect of the Bauhaus movement and emeritus chair of the Department of Architecture at Harvard Graduate School of Design, Walter Gropius.

But the Harvard architecture revival I'm writing about is not that kind of architecture. It was a computer machine architecture in the punched tape era that separated program and data in two different pathways. The Harvard Mark I machine was designed by Howard Aiken at Harvard University. He took inspirations from the Analytical Engine mechanical computer designed by Charles Babbage, who was the mathematics mentor of Ada Lovelace, the first computer programmer and the daughter of poet Lord Byron.

There is poetic justice about the fact that computer programming came out of the conjunction of mathematics and poetry.

What makes Harvard architecture computers notably different from today's computer is that programs were read-only, and data could not be executed as programs. In today's computer, programs and data are stored on the same storage medium. Anyone who can put data on a computer can also run it as a program.

Security breaches happen in two steps: (1) someone has write access to a data path, and (2) subsequently leverages the data path to upload and execute unauthorized programs on a computer they do not own. Gaining write access for step (1) is not that hard. Many computer systems that handle data actively solicit data from non-privileged users. Step (2) relies on having some knowledge of vulnerabilities in a running program that can trick it into passing control flow onto arbitrary data.

Case in point is WordPress, which is a blogging platform notorious for having vulnerabilities that result in security breaches. That's partly because it is built on PHP, a language that makes it easy to run data as program:

  • Once file upload is enabled on a site, PHP will allow it for any script on that site even if that particular script never expects file upload.
  • A moderately complex site breaks down their code into several files, and the first file include() or require() other files to bootstrap the program's functions. The file to be included is a computed path that could be any file on the filesystem.
    • PHP can be configured to limit the path of what could be included using open_basedir. This limits exfiltration of system files that are not part of the public site such as /etc/passwd, but uploaded files are often moved under open_basedir which can then be included.
  • Any file type could be included, even if it is an image file with PHP code embedded in it.

The user only needs to upload a malicious image to WordPress and trick it to run the image. It's less of an issue for a private WordPress installation, but on a shared blogging site like wordpress.com where anyone could register an account, anyone can cause a security breach and steal other people's passwords. That's why people shouldn't reuse passwords on multiple sites.

Once they hijack the computer, they also hijack whatever data was entrusted to be handled on that computer. They may also modify existing legitimate programs on the computer and hide illicit code there, which makes it very costly to discover and clean up after a security incident. This is how ransomware works in a nutshell. Some crooks turned security breaches into a profiteering criminal enterprise.

If today's computers have separate program and data pathways, security breaches would only be limited to the original unauthorized data path access but would not escalate to become a complete hijack of the computer.

Modern computers provide some facilities to separate code and data, but they are optional and must be deployed judiciously in a production environment in order to be effective.

  • Executable space protection designates parts of the memory only for handling data and prohibits executing it as code. This protects programs that are already running from remote code injection vulnerabilities.
  • Enforce writable data to be non-executable (i.e. W^X). This is typically part of the executable space protection for running programs, but the same principle can be applied to programs and data stored on disk.
  • Copy on write is a storage policy that maintains snapshots of data modifications. This can make it easier to restore the filesystem to a former state before the security breach.
  • Some operating systems support making a filesystem read-only, e.g. read-only bind mounts.
  • Some filesystems have the option to make files non-executable on a volume, e.g. zfs exec=off, noexec mount option.
  • Code signing verifies that a program comes from a trusted party and has not been modified in an unauthorized manner. Verification and execution must happen atomically. Otherwise an attacker has an opportunity to modify the program between verification and execution to evade detection.
They all work towards the same principle as Harvard architecture, where program is read-only, and writable data cannot be executed as program.

    Ultimately, the reason why programs must be read-only has to do with accountability requirements imposed by Sarbanes-Oxley Act in response to corporate scandals such as Enron. Programs running in production must be able to establish its provenance, and that someone has reviewed and certified that the program serves its intended purpose. If the program is writable after the certification, then that would put its provenance in doubt.

    In a sense, if a company falls victim to ransomware attack, there must be a loophole in the accountability of its information systems. Revival of Harvard architecture would close the loophole and eliminate ransomware attacks.

    Saturday, November 28, 2020

    My notes for setting up a new Yubikey 5

    A hardware crypto token such as Yubikey is not meant to be used forever. A new release would address old vulnerabilities and add new crypto support. The firmware is not upgradable (for security reasons), so new features and fixing vulnerabilities always require the key to be replaced. It is already a toil for anyone to rotate their hardware token with all the servers they might have used it with for authentication. If they had used a hardware token to encrypt data for long term archival, the hardware token could not be disposed without re-encrypting all data. Cloud service providers can afford to engineer a solution that uses static derived keys encrypted by a master key that could be more easily rotated, but I'm not aware of off-the-shelf solutions for individuals. As such, I do not recommend using hardware tokens such as Yubikey to encrypt archived data.

    Even though I don't use Yubikey for encryption, there is still considerable effort to set it up for authentication which is my primary use for it. In this article, I will explain the feature landscape of different crypto key types, followed by a step by step instruction how I configured my key. Hopefully it helps you decide if this is the right time to start using Yubikey or upgrade your existing key, and if it is the right time, how to do it.

    Background

    My own motivation is to replace my RSA key with ECC key because ECC 256-bit key is shorter and has roughly the same strength as RSA 3072 bit key (here is a rationale that I endorse). However, the NIST P-curves are not safe. There are some criteria for establishing the safety of various ECC curves, courtesy to the author of curve25519.

    First of all, a cautionary tale: don't order Yubikey 5 from Amazon. I made the mistake of ordering one there in April 2020, and I got a Yubikey with an old 5.1.2 firmware (it wasn't discounted). The new firmware 5.2.3 was released in August 2019, a handsome 8 months ago. Amazon also refused to post my warning about the old firmware as a review because they said it pertains only to a specific supplier, not the product.

    Starting from firmware 5.2.3, Yubikey implements OpenPGP specification 3.4 which added support for ed25519 keys, among other ECC types. However, NIST P-curves (known as "ecdsa" in SSH) and ed25519 are the only new ones that work with SSH. The new firmware also added OpenPGP attestation which certifies that a key is generated on chip, and whether touch is required to use the key (attestation was first introduced in U2F).

    The old 5.1.2 firmware lacked ed25519 support. It was to replace my Yubikey 4 which generated weak RSA keys. Before that, I had a Yubikey NEO-n which lacked touch support for OpenPGP even though U2F always required touch. Yubico is already working on implementing biometric touch for the next generation Yubikey.

    Also, the software tools provided by Yubico changed over time. The previous generation tools Yubikey NEO Manager and Yubikey Personalization Tool have been deprecated and replaced with Yubikey Manager. It is worth noting that the GUI version only lets you configure FIDO2 and PIV, not OpenPGP. However, a CLI version is bundled with the GUI version, and the CLI has the OpenPGP configuration options. At one point, it was only possible to configure OpenPGP touch policy with a third-party script yubitouch, but it should not be used anymore.

    That said, the entire ecosystem around using OpenPGP hardware key to login over SSH is pretty fragile in my opinion. It involved several parties to be perfectly aligned: Achim Pietig who rectifies the OpenPGP specification, the GnuPG team which is mostly just Werner Koch and sometimes NIIBE Yutaka (who designed the Gniibe Gnuk key), Yubico and other hardware vendors, the OpenSSH developers who decide which new key types to support, and the various distributions that decide which versions of GnuPG and OpenSSH are available to the end user. Since OpenSSH 8.1 added FIDO/U2F support, once this is rolled out to the various OS distributions, OpenPGP should not be used with SSH anymore. OpenSSH 8.4 was only accepted into Debian Buster backports two days ago, and before that Buster only had OpenSSH 7.9. Mac OS X Big Sur finally has OpenSSH 8.1. Both client and server need to support U2F over SSH in order to work.

    Step by Step Guide

    Without further ado, here is what I did to set up my Yubikey 5 on Mac OS X.

    First, make an alias for the ykman command. The slash escape is needed in order for the alias to observe the whitespace in the path.

    $ alias ykman='/Applications/YubiKey\ Manager.app/Contents/MacOS/ykman'

    Disable Yubico OTP, otherwise accidental touches will cause the passcode to be typed as if someone was typing it on the keyboard. It appears as a string of random characters.

    $ ykman config usb --disable OTP

    Initialize the card first with gpg --card-edit before configuring OpenPGP touch policy. That's because generating new keys will cause the touch policy to be reset to OFF. Here is a condensed recipe followed by some explanations.

    $ gpg --card-edit
    > admin
    > factory-reset # see NOTE(1)
    > kdf-setup # see NOTE(2)
    > passwd # see NOTE(3)
    > key-attr # see NOTE(4)
       (2) ECC
       (1) Curve 25519
    > generate # see NOTE(5)
    Make off-card backup of encryption key? (Y/n) n
             0 = key does not expire
    Key is valid for? (0)
    Key does not expire at all
    Is this correct? (y/N) y # see NOTE(6)

    # Optionally:
    > name
    > url
    > login

    Notes:

    1. factory-reset does not require PIN. It only resets the OpenPGP applet and will leave FIDO U2F intact. However, it does not reset the OpenPGP attestation touch policy. This only needs to be done when I f'd up and need to start over.
    2. kdf-setup prevents plain text PIN from being sent over USB.
    3. first change Admin PIN (3), then change PIN (1). Note that PIN does not have to be numeric. I have my Admin PIN set to my login passphrase. Many key configuring operations require both PIN and Admin PIN, and Admin PIN can be used to override PIN, so both must be set for security reasons.
    4. key-attr will repeatedly prompt for signature, encryption, and authentication keys. It will ask for Admin PIN each time. Again, only Curve 25519 is supported by SSH. Only the authentication key is used by SSH, so signature and encryption keys could be other types.
      • Since SSH does not support secp256k1, using it will cause "Agent refused operation" error with SSH.
      • The key types that SSH does not support are hidden unless the session was started in expert mode using gpg --card-edit --expert.
    5. generate will first ask for PIN, then ask for user information, then ask for Admin PIN prior to key generation. Again, generation of new keys will reset the touch policy.
      • Do not make off-card backup. The key will be generated off-card first and then loaded back to Yubikey, which means OpenPGP attestation won't work.
    6. There seems to be no point in setting a key expiration here. The expiration can be changed using gpg --edit-key (note: this is a different session mode than --card-edit) after the key is generated.

    Now we need to configure the OpenPGP touch policy. There are a few oddities to be aware of before proceeding.

    • Firstly, after running gpg --card-edit, the ykman command seems to hang, but unplugging and replugging the Yubikey makes it work again.
    • Secondly, ykman seems to have trouble disabling terminal echo on Mac OS X ("Can not control echo on the terminal" with a GetPassWarning), so the PIN and Admin PIN will be echoed to the screen. It is using the Python getpass module, which works when I run it in Python directly. I think ykman wasn't able to import termois because the code signing prohibited it from loading dynamic libraries.
    • Lastly, file output could not be written, possibly due to Catalina's enhanced security policy. Writing to standard output works, but beware that prompts are also written to stdout. It means that output redirected to a file would be polluted with interactive messages. They should read my article To err is human; to out, pipeline.

    Now, use ykman to set touch policy. It will ask for the Admin PIN.

    $ ykman openpgp set-touch SIG FIXED
    $ ykman openpgp set-touch ENC FIXED
    $ ykman openpgp set-touch AUT FIXED
    $ ykman openpgp set-touch ATT FIXED

    Note: set-touch ATT FIXED only needs to be done once per Yubikey ever. This is not affected by factory-reset. Trying to set it again will result in a harmless error.

    Finally, I am generating the OpenPGP attestation certificates but haven't found a use for them. The ones generated by Yubikey contains an X.509 v3 extension also indicates what the touch policy is, so an external trust engine may use it to decide whether to give an attested key more trust. Note that unless the touch policy is FIXED or CACHED-FIXED, it can be changed to OFF later, so it makes no sense to attest any other touch policies.

    These will ask for the regular PIN and write the attestation certificate to standard output.

    $ ykman openpgp attest SIG -
    $ ykman openpgp attest ENC -
    $ ykman openpgp attest AUT -

    After each command, copy and paste the X.509 certificate to its own file. Do not attest ATT which is the attestation key. I suspect it will destroy the preloaded attestation key but haven't tried it. It will warn you that it will overwrite an existing attestation certificate. Yubikey comes with an attestation key preloaded which certifies that the OpenPGP keys are generated by a Yubico manufactured hardware. If the attestation key is overwritten, it could no longer be recovered even after a factory reset.

    I use GPG Tools on Mac to add a photo to the key which has a nicer interface, but gpg --edit-key should work. Although the recommended photo size is 120x150, I find that 240x240 produces the best result. It will be scaled down to 120x120 by GnuPG. After this, the public key is ready to be exported.

    Old public keys need to be revoked and exported again. The newly exported key will then contain the revocation certificate.

    The new key should show up in ssh-add -L without further action. If not, make sure SSH_AUTH_SOCK points to gpg-agent, not launchd. Usually starting a new shell after running gpg --card-edit will do the trick. The output of ssh-add -L contains the public key (identifiable by the cardno which is the Yubikey's serial number) that needs to be added to $HOME/.ssh/authorized_keys on the SSH server.

    Monday, November 23, 2020

    pidfd_getfd is harmful!

    Everyday, it seems like Linux is gaining more Windows features to allow one process to hijack another process, which enables computer viruses and malware to propagate and steal user data. A recent example is the addition of pidfd_getfd(), a system call that lets one process duplicate a file descriptor belonging to another process. The idea is that process Mallory would inspect procfs and see which file descriptors process Victim has open, then Mallory can duplicate them at will.

    Before pidfd_getfd(), regular files may be reopened via procfs. It works even if the file has been unlinked, although the opening is still subject to inode permission. It may not seem like a big deal, but file permission controls access by the owner user and group, so it could not let one process keep secret from another process belonging to the same user, or from root. Fortunately, sockets and pipes cannot be reopened from procfs.

    There are some questionably legitimate uses for pidfd_getfd(), but this mechanism is flaky. A commentator on LWN already pointed out the hilarious confusion due to race condition. There is a delay between Mallory enumerating the file descriptors in procfs and when it decides to steal a file descriptor. In the mean time, Victim could have duplicated another file to it (e.g. via dup2()).

    Here is the real reason why pidfd_getfd() is harmful: it violates the assumption in POSIX that a file descriptor is a credential testifying that a process has access to some resource. This credential can be passed around using sendmsg() with SCM_RIGHTS, or inherited by a child process through fork(). Both of these are deliberate actions taken by someone who possesses the credential. Now the security model is weakened to allow anyone who can call pidfd_getfd() to gain unauthorized access to these resources. It's unauthorized because it lacks deliberate action by the credential owner.

    Before, a process could create a socketpair() and be secure in the knowledge that only the process it shares the file descriptor with can communicate over this secure local channel. Since the socket pair is already connected, it cannot be connected to another socket. But pidfd_getfd() allows Mallory to access the secret channel between Alice and Bob.

    Before, Alice could send a file descriptor for a file she owns to a specific process owned by Bob even though Bob normally couldn't open the file. Another process owned by Bob would not be able to reopen that file from procfs. However, pidfd_getfd() bypasses the file permissions check.

    An important principle in designing a secure system is to disallow access or an operation by an outsider unless a deliberate action is taken by the owner of the resource. Unfortunately, pidfd_getfd() breaks that principle. It was introduced in Linux kernel 5.6, so versions henceforth are no longer secure by design.

    Saturday, February 6, 2016

    Generic setuid/setgid wrapper for scripts

    The setuid or setgid bit on a binary executable allows the binary to run with the effective uid or gid set to the owner of the executable, rather than the user that runs it. It is a rudimentary way for anyone to impersonate as the executable owner, so the owner can provide limited services using the owner's identity, including using files only accessible by the owner.

    Historically, system binaries such as /sbin/ping are setuid root since ping requires privileged network access, but capabilities have reduced those needs. Binaries that manipulate privileged files still need to be setuid root, such as /bin/passwd. To setuid non-root user is less common but is still useful to control filesystem access.

    Sometimes it is useful to write a shell script and making it setuid or setgid for the sake of controlling filesystem access. Many experts generally warn against setuid shell scripts. Here are the common security issues specific to scripts.
    • Anyone could create a symlink that resembles shell options and obtain an interactive shell with elevated privileges.
    • Anyone could create a symlink to a genuine setuid script, then after the OS executes the interpreter, perform a symlink switcheroo to a malicious script.
    • Command line interpretation can be changed by PATH or IFS.
    Some people advocate (warning: bad advice) creating a binary specifically for executing the shell, but it can render other safety guards ineffective. The dynamic loader is more careful with the LD_PRELOAD and LD_LIBRARY_PATH directives with a setuid executable. But in this case, only the wrapper binary is setuid, but the shell run under is not, so it will pull in the whole slew of dynamic loading hooks unless we sanitize the environment.

    One technique that an OS overcomes the switcheroo problem is to open the script file and pass /dev/fd/N to the interpreter, which ensures the same file is seen by the OS and the interpreter. This must be explicitly enabled on the OS and is still ignored by Linux. At least on Mac OS X, the interpreter's own setuid bit is also ignored.

    When it comes to my own need, it basically boils down to:
    1. Don't bother with setuid/setgid, but use sudo which sanitizes environments. My use case is most similar to the line "ALL ALL = (script-owner) NOPASSWD: /path/to/script" in /etc/sudoers, to be run as "sudo -u script-owner /path/to/script". But sudoers manual begins with a "Quick guide to EBNF" which scares me.
    2. Rewrite my shell script as a full blown C program. I'm not feeling overly excited about that.
    3. Write a setuid/setgid wrapper binary in C, and the rest as shell script.
    Needless to say, I took the last approach.

    ps. In doing this, I found out about the shortest open source license called "Fair License" which is appropriate for such a short program.

    Thursday, July 23, 2015

    Tweet sized Mac OS X 10.10 exploit

    It took me a while to understand what this exploit is doing, so I thought I would make a note for my own benefit and for others.
    echo 'echo "$(whoami) ALL=(ALL) NOPASSWD:ALL" >&3' | 
    DYLD_PRINT_TO_FILE=/etc/sudoers newgrp; sudo -s # via reddit: numinit (shorter)
    The entire line is a shell command that adds the current user to the /etc/sudoers file and grants it sudo access without password, then runs sudo to escalate to a shell with root privilege. The greyed out part is the comment. But how it accomplishes this is very clever.

    Here is what the rest of the code does: newgrp is a command that starts a command line shell after setting or resetting the effective group. It is a setuid root program which means it runs with escalated root privilege, but newgrp only runs the sub-shell after downgrading the privilege back to the current user and the desired group. The shell interpret commands from its standard input, so this fragment pipes a command to the sub-shell which runs it.
    echo 'echo hello' | newgrp
    The sub-shell started by newgrp runs the command echo hello which prints out hello to the terminal. In the exploit, the command passed to the sub-shell is echo "$(whoami) ALL=(ALL) NOPASSWD:ALL" >&3 which writes a sudoer line for the current user to file descriptor 3.

    How does file descriptor 3 come into play? When you run newgrp with the environment variable DYLD_, it gets interpreted by the dynamic loader (dyld) with a specific meaning. The purpose of the dynamic loader is to piece a program together from different parts. It runs as the same privilege of the program.

    On Mac OS X 10.10, the man page describes DYLD_PRINT_TO_FILE as follows.
    DYLD_PRINT_TO_FILE
    This is a path to a (writable) file. Normally, the dynamic linker writes all logging output (triggered by DYLD_PRINT_* settings) to file descriptor 2 (which is usually stderr). But this setting causes the dynamic linker to write logging output to the specified file.
    Before dyld could write to a file, it has to open the file and obtain a file descriptor. Here DYLD_PRINT_TO_FILE=/etc/sudoers tells dyld to open /etc/sudoers which is normally only writable by root. It succeeds because dyld runs as root since newgrp is setuid root.

    In the usual case, file descriptors 0, 1, 2 are reserved for standard input, standard output, and standard error, so the next available file descriptor is 3 which is assigned to the newly opened file. Now dyld is not told to actually write anything, but it leaves the file descriptor 3 open. Unless file descriptors has O_CLOEXEC (see open), they are kept open across fork() and exec() which are system calls for starting a new program. The same file descriptor, now with access to a file that normally root can open, is seen by the sub-shell run by newgrp even though the sub-shell is not root.

    The command run by the newgrp sub-shell then modifies /etc/sudoers so that the current user could run sudo without a password, by writing the line to file descriptor 3.

    There are several ways to block this exploit.
    • dyld should strip all DYLD_ environment variables if it realizes that the current program is setuid. This is the approach taken by the Linux dynamic loader. These environment variables alter the behavior of dyld, which is undesirable for setuid programs.
    • newgrp should close all file descriptors except 0, 1, and 2 before running the sub-shell. Most of the times, file descriptors are not intended to be passed around across processes.
    • newgrp could also close file descriptor 0 (standard input) and instead reopen the controlling terminal. This disallows passing command via standard input.
    • In general, setuid programs that start a sub-shell should not do so without requesting password from the terminal. Programs like login, su, and sudo are generally okay.
      • Command to find setuid root programs: find /bin /usr/bin /sbin /usr/sbin -user root -perm -4000
    • The open() call might instead randomize the file descriptors returned. Conventionally it always uses the lowest numbered file descriptor, but this has no tangible benefit.
    • DYLD_PRINT_TO_FILE could open the file using O_CLOEXEC. When the current program starts a child process, the current file descriptor would be closed, but the dyld of the child process will see this environment variable again and attempt to open it using the appropriate credentials of the child. As long as the file is opened in append mode, the parent and child can both write to the same file atomically without overwriting each other's content.
    Doing all will prevent any of these components from becoming part of a pathway for a future exploit.

    Friday, February 13, 2015

    Crypto Ecosystem

    The crypto stack is complicated. There are many APIs and implementations of the same API. There are different ways the components could be configured to interact with each other. Here is my attempt at visualizing the various relationships of the crypto ecosystem.

    Here is the original drawing.

    The depicted components:
    • Applications: Chrome, Firefox, GnuPG, Keychain Access, OpenSSH.
    • APIs and protocols: CCID, PC/SC, PKCS#11.
    • Smart card drivers: CryptoTokenKit, OpenSC, *.tokend.
    • Hardware: PKCS#15 card, OpenPGP card.

    Friday, October 24, 2014

    Cross-Site Request Forgery Prevention

    Cross-site request forgery (CSRF or XSRF) happens when an attacker embeds a tag like <img src="http://snafu.com/cgi-bin/delete_account?confirm=yes"> in a malicious web page on attacker.com. When user visits the page, authentication cookies are sent to snafu.com despite the page origin. Forms that POST to snafu.com can be embedded in a malicious page as well. "Referer" can be forged if snafu.com redirects to canonicalize URL.

    One solution to prevent the attack is to both: (1) use an unguessable secret cookie rotated regularly, and (2) require the same secret to appear in the POST request as a hidden form field.

    If the secret appears in the URL, and if the attacker may embed content in snafu.com, then when snafu.com loads a page on attacker.com, the "Referer" header would reveal the secret.

    Source: https://www.owasp.org/index.php/Cross-Site_Request_Forgery_(CSRF)_Prevention_Cheat_Sheet